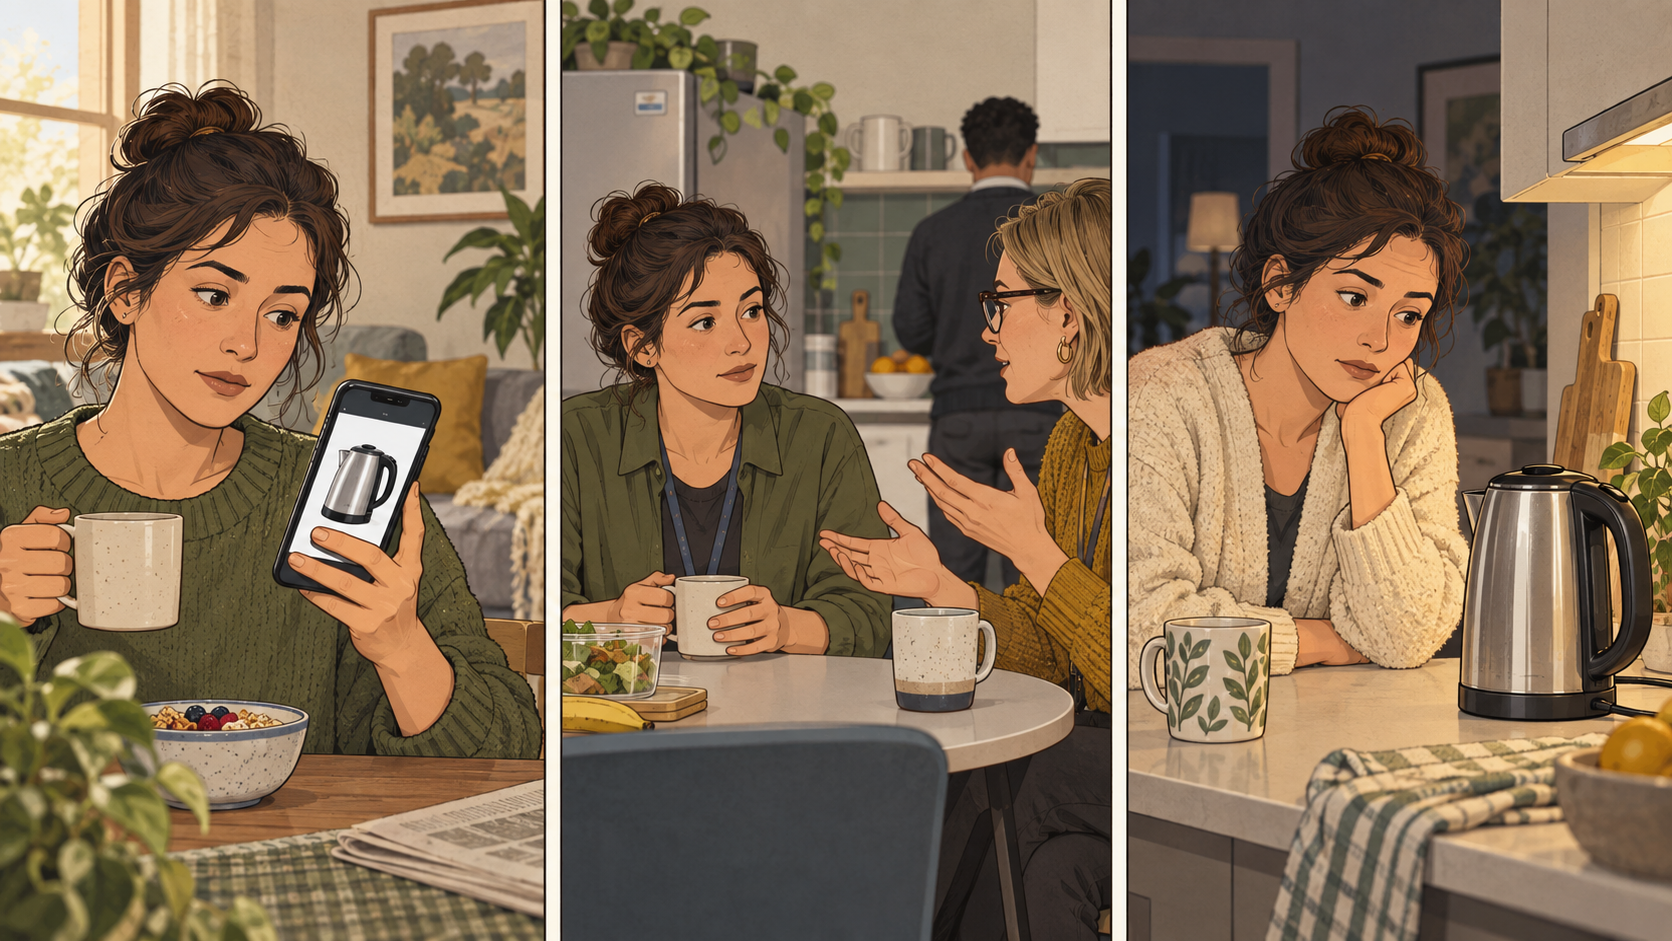
Two hosts, one increasingly suspicious kettle, and a conversation across the whole issue.
Read the conversation
One complaint, several appearances
Listener: Someone posts that their kettle broke after two weeks. A colleague repeats it at lunch. Now I'm looking at my own kettle thinking: questionable character.
Explainer: What new evidence arrived at lunch?
Listener: A sandwich. And apparently the same post.
Explainer: Then you've encountered the claim twice. You haven't necessarily gained a second witness.
Listener: The kettle has acquired a reputation without acquiring a second complaint.
Explainer: Exactly. That's the question running through this issue: what reached you, what did you add to it, and what would justify acting on it?
Listener: So before I replace a perfectly working appliance, we investigate the evidence. A difficult day for online shopping.
Familiar is not independently checked
Explainer: Research on the illusory truth effect finds that repetition can increase perceived truth on average. That doesn't mean a claim becomes true on its fourth appearance. There isn't a loyalty card.
Listener: Hear nine rumours, believe the tenth free.
Explainer: Nor does it mean everyone responds the same way. Fazio and colleagues found repetition effects even for some statements participants had knowledge to answer correctly.
Listener: Knowing things helps, but apparently it doesn't grant diplomatic immunity from nonsense.
Explainer: Right. With our kettle, find the original complaint. Then ask whether other reports are independent, whether it's the same model, and how common the fault is. A vivid example doesn't supply a failure rate.
Did you supply the answer?
Listener: Fine. I'll ask AI: why are these kettles so unreliable?
Explainer: You've put the verdict in the question.
Listener: Very efficient. Saved it the inconvenience of finding out.
Explainer: Compare that with: what evidence would show this model is unreliable? Research finds that prompt framing can change model answers. Separate experiments found that overly agreeable AI responses could strengthen people's conviction in personal disputes.
Listener: So if I ask why my boss hates me, an elegant answer isn't proof my boss hates me.
Explainer: Ask what other explanations fit and what would distinguish them. Then check the sources outside the chat. A more neutral question helps you investigate; it doesn't guarantee a correct answer.
Who selected the conversation?
Listener: But everyone in my feed is talking about the kettle.
Explainer: Everyone in your feed is a selection. A service ranks posts, and you choose accounts to follow. Neither gives you a census of humanity.
Listener: My phone has been appointed spokesperson for eight billion people. Bold promotion.
Explainer: Australia's September proposal, My Feed, My Way, raises the question of user control over that selection. At this issue's evidence cutoff, it was a proposal, not a right already in force.
Listener: Would choosing a feed of followed accounts solve misinformation?
Explainer: Your friends can share a bad claim too. A different feed can change what you encounter. Whether it changes what you believe is another question.
A familiar picture can distort scale
Listener: Speaking of familiar pictures: Greenland. On some maps it looks ready to take on Africa.
Explainer: Africa has about fourteen times its area. Mercator stretches areas toward the poles while preserving angles useful for navigation.
Listener: Greenland has excellent representation.
Explainer: The UN's Correct the Map resolution encourages area-preserving maps when relative size matters. It didn't ban Mercator or invent a map that's best for every job.
Listener: So I ask what the picture preserves, not just whether it looks normal.
Explainer: Exactly. Changing a projection fixes the displayed area comparison. Whether it changes someone's broader beliefs needs evidence of its own.
Seeing a scene is not proving an event
Listener: What if the picture shows something that never happened at all?
Explainer: Brazil's election rules address synthetic campaign material and prohibited deepfakes. The legal category matters. Not every use of AI is the same offence.
Listener: A sentence that is unlikely to fit on an outraged thumbnail.
Explainer: A monitoring report described suspicious material it collected. That sample doesn't tell us the proportion of all election content that's synthetic, or how anyone voted because of it.
Listener: And removing a clip doesn't tell us whether everyone who saw it also saw the correction.
Explainer: That's something to investigate: what spread, what correction followed, and who encountered each. We shouldn't invent an election effect because the possibility sounds plausible.
Who got to ask the question?
Listener: You can also change what people hear by changing who's allowed in the room.
Explainer: The issue follows the White House access dispute involving CNN, MS NOW and Politico. September reporting described temporary court protection while the dispute continued. It wasn't a final judgment on everything alleged.
Listener: Temporary order. Final headline. A familiar administrative error.
Explainer: There's also separate reporting about government advertising. Access to ask questions and money spent promoting an account are different mechanisms. Both can affect what's available to encounter.
Listener: But neither tells us what a viewer ended up believing.
Explainer: Correct. Watch the court record, who can attend and question officials, and what is actually purchased and distributed. Don't merge separate records into one convenient motive.
The tent ad needs more than a theory
Listener: I mention camping and a tent ad appears. Surely my phone listened.
Explainer: The timing alone can't establish that. Google, Apple and the FTC describe other routes: searches, visits, app tracking, location and inferred interests.
Listener: So the ad may have found me through the forty tents I looked at yesterday. An astonishing breakthrough in espionage.
Explainer: Perhaps. But we haven't reconstructed your particular ad. The point is to compare explanations, not replace an unsupported microphone claim with an equally unsupported certainty about something else.
Listener: Observation: tent ad. Explanation: still investigating.
Explainer: Then inspect the advertising information and app permissions. Those can offer clues, though not a complete history of that ad.
Five years between which tests?
Listener: Health Lens asks a different question: why did Australia move from Pap smears every two years to cervical screening every five? The numbers alone sound like less checking.
Explainer: The test changed. Pap tests looked for abnormal cells. HPV screening looks for the infection responsible for almost all cervical cancers. A negative result puts eligible people at low risk over the following five years, which supports that routine interval.
Listener: So comparing two with five without comparing the tests leaves out the actual explanation.
Explainer: Yes. Routine screening generally covers people with a cervix aged twenty-five to seventy-four who've had sexual contact. Prior results and medical history can change the follow-up schedule.
Listener: And there's a self-collection option?
Explainer: For eligible screening, a vaginal swab can test for HPV as accurately as a clinician-collected sample. But it can't also check cervical cells. If other high-risk HPV types are detected after self-collection, you generally need to return for a clinician-collected sample to decide the next step. Don't assume every positive result means wait twelve months.
Listener: That's the part I would want clearly explained before leaving the appointment.
Explainer: And symptoms such as unexpected bleeding or unusual persistent discharge need assessment. Don't wait for a routine reminder, even after a negative screen.
What did the words add?
Listener: We also have fifty headlines to compare. Finally, a modest amount of internet.
Explainer: Headline Lens groups them around eight stories. Look at the verbs, the attribution, and whether an allegation has become a fact between the source and the headline.
Listener: Three outlets repeat the same wire report. Three independent confirmations?
Explainer: Three appearances may still share one reporting source. Trace it. And don't infer a writer's motive from one verb.
Listener: The Atlas then connects the stories?
Explainer: It explains particular connections and their limits. Similar questions don't mean one story caused another. The consequences sections ask what could follow, what conditions matter and what evidence would change the assessment.
Back to the kettle
Listener: Back to my kettle. One complaint, repeated at lunch. I can check the model, look for independent reports and see whether there's an actual recall. I don't need to declare it innocent or guilty over a sandwich.
Explainer: That's the useful pause. What did you encounter? What did you infer? What supports the next thing you plan to do?
Listener: And if the evidence changes, I can change my mind without treating it as a personal administrative failure.
Explainer: The full issue, Health Lens, headline comparisons and original sources are at lens dot zakgov dot com.
Listener: I'll put the kettle on. Its performance review is still open.